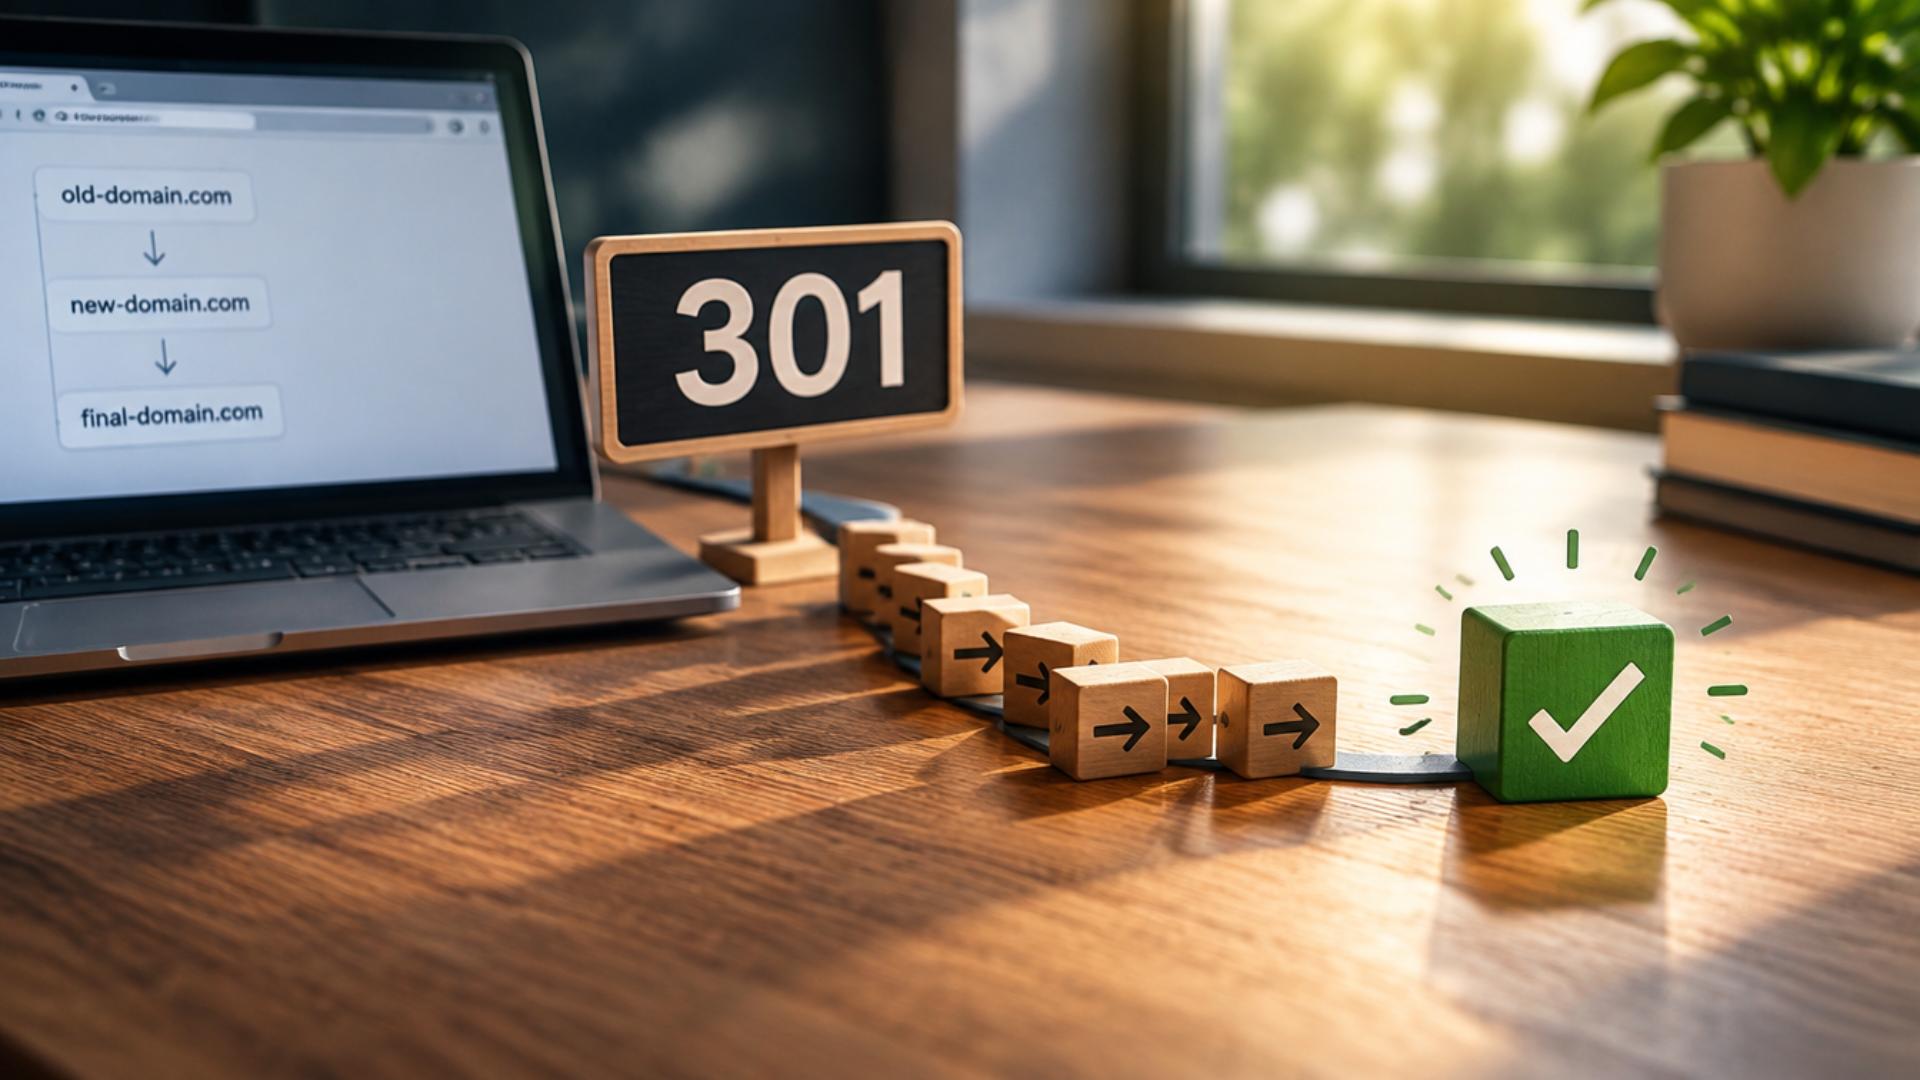
301 redirects are essential when a page permanently moves, but they can become a crawling concern when a website relies on inefficient redirect paths. A single redirect to the correct destination is generally not a problem. The bigger issue is when redirects form chains, loops, or involve many outdated URLs that Google must process. For larger websites, these unnecessary crawling steps can make it harder to use available crawl capacity efficiently. Understanding where redirects create real crawl inefficiencies helps site owners keep URL structures clean without avoiding 301s that are necessary for SEO.
How 301 Redirects Use Crawl Budget
When Googlebot requests a URL that returns a 301, it does not receive the final page immediately. The server first tells the crawler that the URL has moved permanently and provides the destination. Googlebot then processes that redirect and requests the target URL.
A single redirect adds an extra step, but that alone is not a significant crawl-budget problem. The concern grows when a site has many unnecessary redirects or when one URL passes through multiple redirects before reaching its final destination. On a large website, these extra requests can consume crawling resources that could otherwise be used to discover or revisit useful pages.
What happens when Googlebot encounters one 301?
Consider a page that has moved from:
example.com/old-page → example.com/new-page
Googlebot requests the old URL and receives a 301 response pointing to the new one. It then requests the new URL and can process the page there.
The key point is that site owners don’t need to avoid the redirect itself. A permanent URL change is exactly when a 301 is appropriate. The SEO concern is whether the redirect structure creates unnecessary additional work.
What happens when Google repeatedly crawls the redirected URL?
Google can keep encountering a redirect when it discovers or revisits the old URL. This is why maintaining a clean URL structure matters, particularly on larger sites with many historical URLs.
The goal is not to eliminate legitimate 301s. It is to make the path from an old URL to its final destination as direct as possible. This becomes increasingly important when a site has many URLs or changes frequently, where inefficient crawling can have a more noticeable effect.
When 301 Redirects Have a Meaningful SEO Impact on Crawl Budget
A 301 becomes more relevant to crawl efficiency when it is part of a larger URL structure rather than an isolated redirect. The effect depends on how many URLs are involved, how many steps Googlebot must follow, and how often those URLs need crawling. This is why the same redirect setup can be insignificant on a small site but more important on a large site with thousands or millions of URLs.
A single 301 redirect
A direct redirect from an old URL to its final destination is generally the cleanest setup:
/old-page → /new-page
One redirect step leads to the destination page. Google recommends permanent redirects when a page has moved permanently, so the goal isn’t to avoid 301s altogether. The goal is to ensure necessary redirects lead directly to the correct destination.
Large numbers of redirected URLs
A website can legitimately have many redirects after redesigns, URL changes, product removals, or migrations. The number alone doesn’t indicate a crawl-budget problem.
The more important question is what Google has to do with those URLs. A large site with extensive historical URLs may require more crawling simply to process old addresses and their destinations. That makes unnecessary redirects more worth addressing than they would be on a small site.
Redirect chains
The clearest problem occurs when one redirect leads to another:
/old-page → /previous-page → /current-page
Each additional hop creates another step before Google reaches the final destination. Google specifically recommends avoiding long redirect chains because they can negatively affect crawling. A direct redirect is more efficient:
/old-page → /current-page
Redirect loops
A loop is more serious because the crawler cannot reach the intended page:
/page-a → /page-b → /page-a
Instead of reaching useful content, Google encounters a repeating redirect path. Fix these configurations rather than treating them as a normal part of a site’s redirect structure.
How Redirect Chains Increase Crawl Inefficiency
A redirect chain creates unnecessary steps between the URL Google discovers and the page it ultimately needs to process. Instead of reaching the destination after one redirect, Googlebot must process each intermediate URL before continuing. For example, /old-page → /category-page → /archive-page → /current-page requires more processing than /old-page → /current-page. The issue is not that the individual 301s are invalid, but that the chain adds avoidable crawling steps.
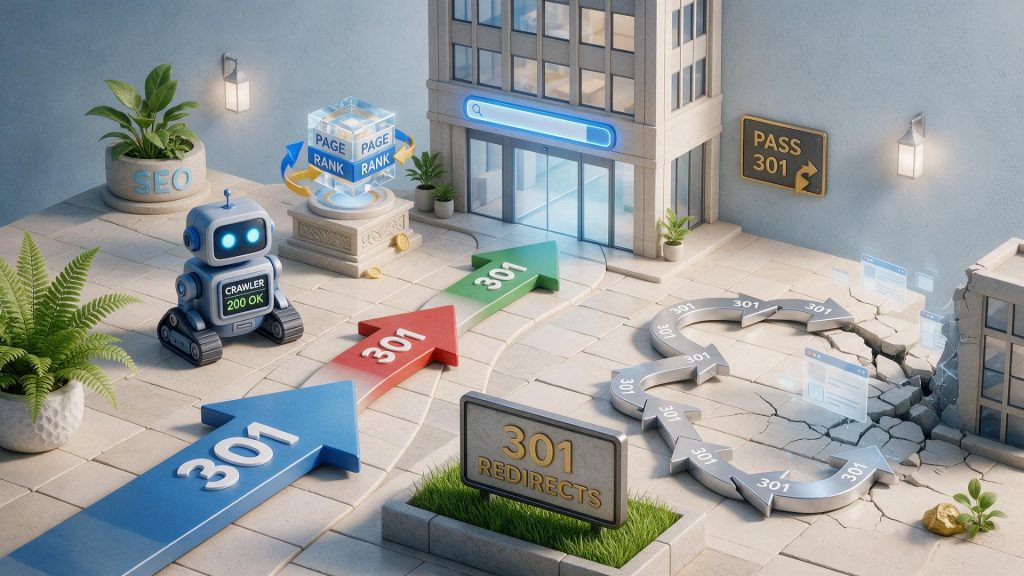
That inefficiency matters more when the same pattern spans a large URL inventory. A single chain is unlikely to have a meaningful effect, but thousands of chained URLs can require Google to process additional redirect responses and destination requests. Chains can also develop when previously redirected URLs are moved again without updating older redirect rules, so regular redirect maintenance is important to keep the path to current pages as direct as possible.
Does a 301 Redirect Waste Crawl Budget?
A 301 redirect does not automatically waste crawl budget. When an old URL permanently moves, using a 301 to send Googlebot directly to the new destination is normal and appropriate. The concern isn’t the redirect itself, but the extra crawling that can result from unnecessary redirect paths, especially when URLs pass through multiple hops before reaching their final destination.
The impact also depends on the website’s size and complexity. A few legitimate redirects on a small site are unlikely to create a meaningful crawl-budget issue. On a large site with thousands or millions of URLs, however, repeated redirect chains or other unnecessary URL paths can create more crawling work at scale. The practical goal is therefore not to avoid 301s, but to keep them direct and eliminate unnecessary steps wherever possible.
How Site Size Changes the SEO Impact of 301 Redirects
The impact of redirected URLs depends heavily on a website’s size and complexity. On a small site, a few necessary 301s are unlikely to create a meaningful crawl-budget concern because Google has relatively few URLs to process. On a large site, however, the same inefficiency can occur across thousands or millions of URLs, making unnecessary crawling more significant.
Google specifically notes that crawl-budget optimization is mainly relevant to very large or frequently updated websites. For these sites, reducing unnecessary redirect steps can help Google spend more of its available crawling activity discovering and revisiting the URLs that matter. This does not mean large sites should avoid 301s; it means redirect structures need to remain efficient as the site’s URL inventory grows.
Other SEO Effects of 301 Redirects That Affect the Bigger Picture
A redirect can influence more than crawling. It also helps Google understand that an old URL has been permanently replaced, which can affect how it consolidates signals associated with the old address with the destination. Consider these effects separately from crawl efficiency.
PageRank and Link Signals
A properly implemented 301 does not inherently cause PageRank loss. Google states that permanent redirects do not cause a loss in PageRank, so the concern should not be based on outdated assumptions that every redirect reduces the value passed to the destination. The more relevant issue is whether unnecessary redirect steps make crawling less efficient.
Indexing and URL Consolidation
A 301 also helps Google understand which URL should represent content that has moved permanently. This can help consolidate signals and guide Google toward the preferred destination. However, the redirect still needs to lead to the appropriate final URL. A complicated redirect path doesn’t provide an SEO advantage just because it eventually reaches the right page.
How to Reduce Crawl Waste From 301 Redirects
The goal isn’t to remove necessary 301s, but to make the path to each destination as direct as possible. This reduces unnecessary processing and helps Google crawl the pages the site actually wants.
Redirect Directly to the Final URL
When a page moves more than once, update the original redirect to point to the current destination. The same principle applies when moving a website from one domain to another: each old URL should point directly to its corresponding destination rather than passing through an intermediate URL.
Remove Unnecessary Redirect Chains
Redirect chains often remain after multiple rounds of URL changes. Review existing redirect rules and replace outdated intermediate destinations with the final relevant URL. This is particularly useful on larger websites where the same pattern may exist across many pages.
Fix Redirect Loops
A redirect loop prevents Googlebot from reaching the intended page. Check for rules that send URLs back to one another and correct the destination so the request can resolve to a valid page.
Update Internal Links
Internal links should point directly to the current URL rather than an address that first returns a 301. This gives both users and crawlers a direct path to the destination and reduces reliance on unnecessary redirect steps.
Keep XML Sitemaps Focused on Final URLs
XML sitemaps should contain the URLs the site wants Google to discover and process, not outdated addresses that simply redirect elsewhere. After a migration or URL restructuring, update the sitemap to the final URLs to give Google a cleaner discovery path.
301 Redirect Crawl Budget Best Practices
- Redirect directly to the final URL. Avoid sending an old URL through multiple intermediate destinations.
- Keep redirect chains short. Review older redirect rules when pages move again to prevent chains from accumulating.
- Fix redirect loops. Make sure redirect rules resolve to a valid destination instead of sending URLs back and forth.
- Update internal links. Point links directly to the current URL instead of relying on a 301 to reach it.
- Keep XML sitemaps current. Use the final URLs you want Google to discover and process, not outdated addresses that redirect elsewhere.
- Review redirects after migrations. Large URL changes can create unnecessary chains or outdated rules if you don’t maintain the redirect structure.
- Focus on actual scale. A few legitimate 301s are rarely a crawl-budget concern; prioritize optimization when unnecessary redirects exist across a large or frequently changing site.
Conclousion
A 301 redirect is a normal part of managing permanent URL changes and does not automatically create a crawl-budget problem. The real concern is unnecessary crawling from redirect chains, loops, and outdated URL paths, especially on large or frequently updated websites. Keeping redirects direct, maintaining clean internal links and sitemaps, and reviewing redirect rules after URL changes helps Google reach important pages more efficiently.